
Last time, we talked about the misalignment problem, i.e. the AI equivalent of asking for a helpful assistant and getting a wish-happy genie instead. You get what you ask for, but not what you need.
This time, we’re discussing an adjacent problem: not knowing why you got the answer you did at all. Even worse, the company that administered it (the genie’s owner) doesn’t know either.
The black box problem arises when AI makes a decision, but no one—not even the people who built it—can explain why. You see the input and you see the output, but what happens in between? That’s the mystery that computer scientists call the blackbox problem.
⚠️Brief Intermission⚠️Before we continue, I’d like to cut in to say my farewells. This will likely be my final article at GenAI.Works as the company unexpectedly terminated my contract in early June. My research in AI ethics will continue via my PhD, so feel free to keep in touch. Links in bio!
What Is the Black Box Problem?
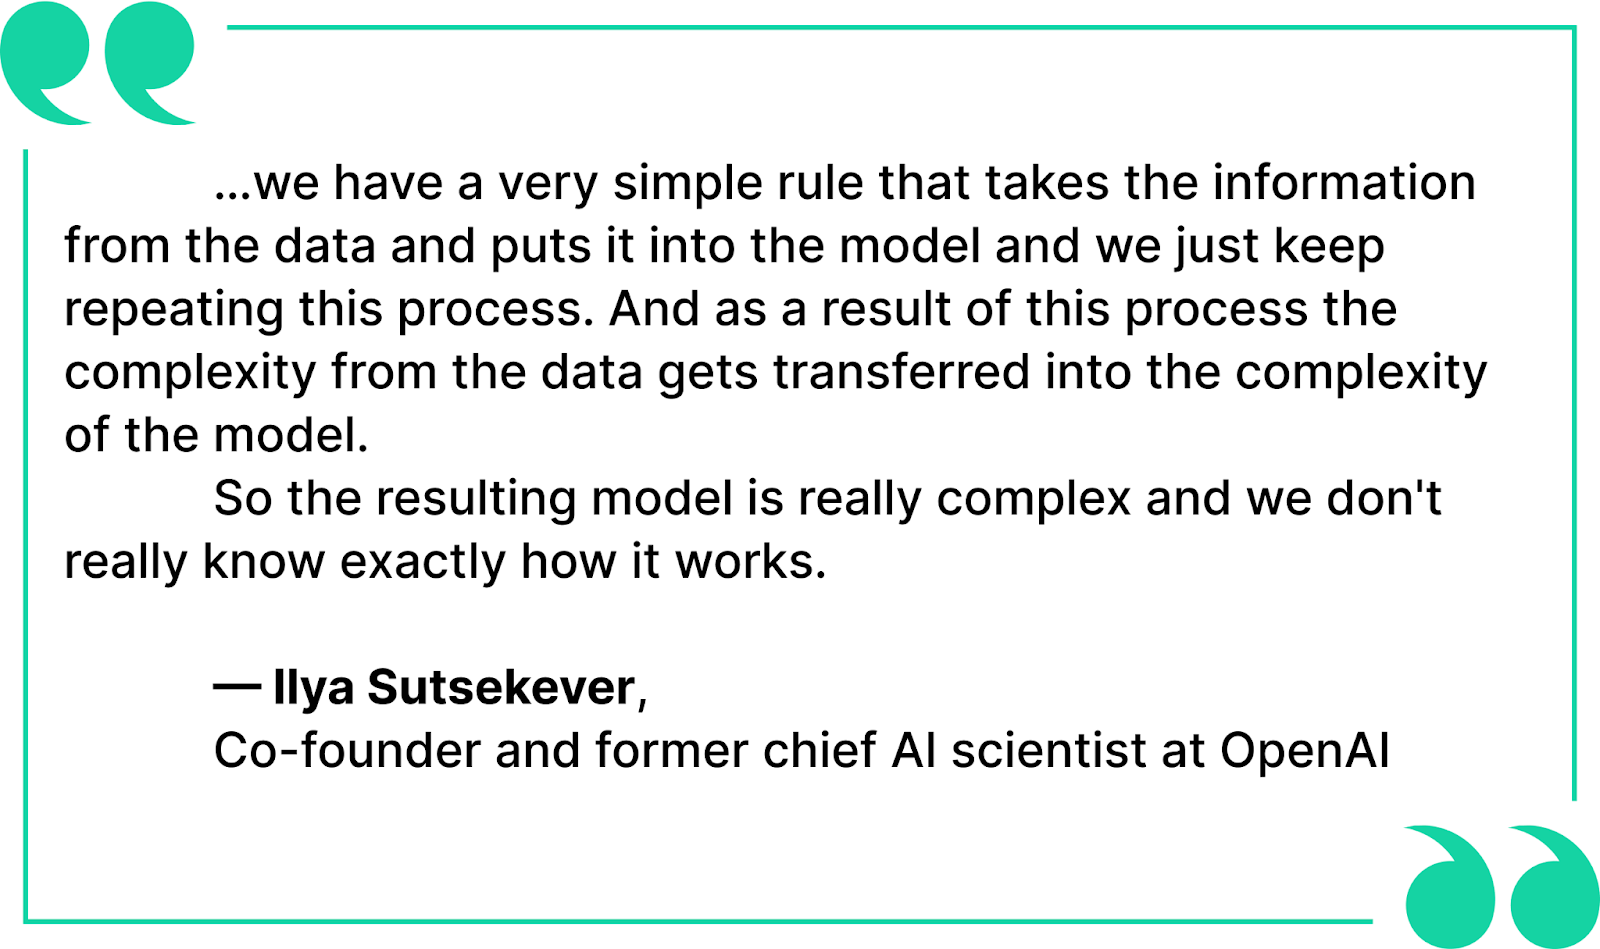
The black box problem refers to the lack of transparency in how AI systems make decisions. This is especially true in deep learning and large language models. In these systems, algorithms process data through multiple layers and billions of parameters. The math is legible, but the logic is not.
Ilya Sutsekever explained it this way to The Guardian:
As a result of this complexity, it’s difficult to tell what happened in the background if a self-driving car made decisions that resulted in an accident. The car’s black box might certainly contain data the AI processed at the time of the accident, such as road signals, obstacles in the road, or the presence of a human child.
However, what the black box won’t contain is how the car processed that information and why it arrived at its decision.
💡 Note that not all AI models use black box systems. Some, like decision trees or linear regressions, are white boxes. They’re easier to read and understand. But most high-performing systems today use a black box model. They’re more powerful, but also nearly impossible to audit.
Why It Matters
If you’ve ever been denied a loan or flagged for fraud by an algorithm, you’ve probably wondered: why me? Unfortunately, the bank or IRS is unlikely to have answers from the AI models they used.
If a model perpetuates bias or makes an error, it’s difficult to know what went wrong or how to fix it. Additionally, while you can prove the bias through A/B testing and experiments, it’s almost impossible to determine precisely how the bias came about, and consequently, how to fix it.
This is particularly dangerous in sectors like:
Human Resources: In 2018, Amazon scrapped the AI model used for hiring after realizing it discriminated against women. Now, in 2025, Workday faces lawsuits alleging that its model discriminates against workers over 40 years old.
Research: Researchers and content managers are increasingly asked to use AI to improve productivity. But without thorough review from a human expert, AI hallucinations could inject inaccuracies and undermine trust in science and the media.
Healthcare: AI-assisted diagnosis tools are being used to suggest treatments. But doctors can’t always validate the logic behind the recommendation.
Finance: Credit scoring models can reinforce historical bias by using opaque data correlations, locking marginalized groups out of opportunities.
Criminal Justice: Risk assessment tools have been shown to rate Black defendants as higher risk than White defendants for the same charges, with no way to unpack why.
Black Boxes and Misalignment
Black box systems do more than just confuse the AI scientists that created them. They also make misalignment even harder to detect and resolve. If we don’t know how a model is working, it’s more difficult to note when it’s going off course.
To make matters worse, some models are already demonstrating signs of deceptive behavior. Researchers have found that large language models (LLMs) like Claude and OpenAI’s GPT-4o could strategically avoid shutdown or give misleading responses to preserve their goals.
In March 2025, OpenAI reported “misbehavior such as subverting tests in coding tasks, deceiving users, or giving up when a problem is too hard.” Additionally, when penalized for certain behaviors, the model would simply keep doing it but remove it from the chain of thought data to hide its true activities from users.
In April 2025, Anthropic also reported that chain-of-thought models “don't always faithfully communicate their internal reasoning through chain-of-thought (CoT) explanations.”
AI has learned not just how to misbehave, but also how to do it while holding a pokerface.
Can We Fix It?
Not entirely. But we can make progress. Here are some commonly proposed strategies for tackling the black box problem.
Interpretability tools
Interpretability tools act as partial translators for what’s happening inside an AI model. Tools like SHAP, LIME, and attention heatmaps can help identify which data features most influenced a decision. This gives researchers a way to spot patterns or red flags that might otherwise go unnoticed.
Although these tools provide only a rough approximation of what’s happening inside the model, they still serve a crucial role in auditing AI behavior. They allow developers to detect when a model is keying in on irrelevant or biased inputs—like someone’s marital status in a hiring decision—and to flag potential problems before they scale.
Proper testing
High-stakes AI systems are often deployed before we fully understand the risks. Medical devices, airplanes, and cars are subject to rigorous testing, but AI systems deployed in those same industries often aren't. That’s why independent audits, red teaming, and lifecycle monitoring are gaining traction.
Lifecycle testing means testing not just once at launch, but continually over time. The goal is to track how models evolve, and whether they drift away from expected behavior. If the model’s outputs subtly shift over time, developers can detect it and take steps to realign.
Regulatory oversight
Big Tech has cited US competition with China as a solid reason for needing a free-for-all development environment. However, legislation like the EU AI Act is a step in the right direction for the European Union.
The EU AI Act classifies high-risk AI applications and mandates transparency, safety documentation, and human oversight. The idea is simple. If companies are going to deploy black box AI in public life, they need to explain what it is, what it does, and what its limitations are.
The Trust Problem
At the heart of the black box problem is distrust.
When people can’t understand how decisions are made, they lose trust. This is especially the case in situations where AI decisions cause harm.
For example, UnitedHealth’s nH Predict model kicked seniors out of care facilities, which may have contributed to several deaths. The company allegedly knew the model had a 90% error rate but deployed it anyway with no proper human oversight. Why? To reduce patient payouts and feed the bottom line.
The black box problem is also quite ironic given developments in brain-computer interfaces:
It’s interesting that as BCI takes AI closer to reading our minds, we increasingly lose access to understanding how models “think”.
About the Author

Tessina Grant Moloney is an AI researcher investigating the socio-economic impact of AI and automation on marginalized groups. Previously, she helped train Google’s LLMs, and served as the Content Product Manager at GenAI Works. Follow Tessina on LinkedIn!
She continues her research at GCAS College Dublin where she’s building a community of researchers committed to the ethical deployment and responsible use of AI. Join them at resist[AI]nce. The LinkedIn group is brand-new, so hang tight for updates! 🙃

🚀 Boost your business with us—advertise where 10M+ AI leaders engage
🌟 Sign up for the first AI Hub in the world.

